
Our software
LoonAI
A private AI, all yours. LoonAI runs open-weights language models — Llama, Qwen, Gemma, Phi — directly on your iPhone's GPU. Download a model once and chat with the network off. No account, no API key, and not one word leaves the device.
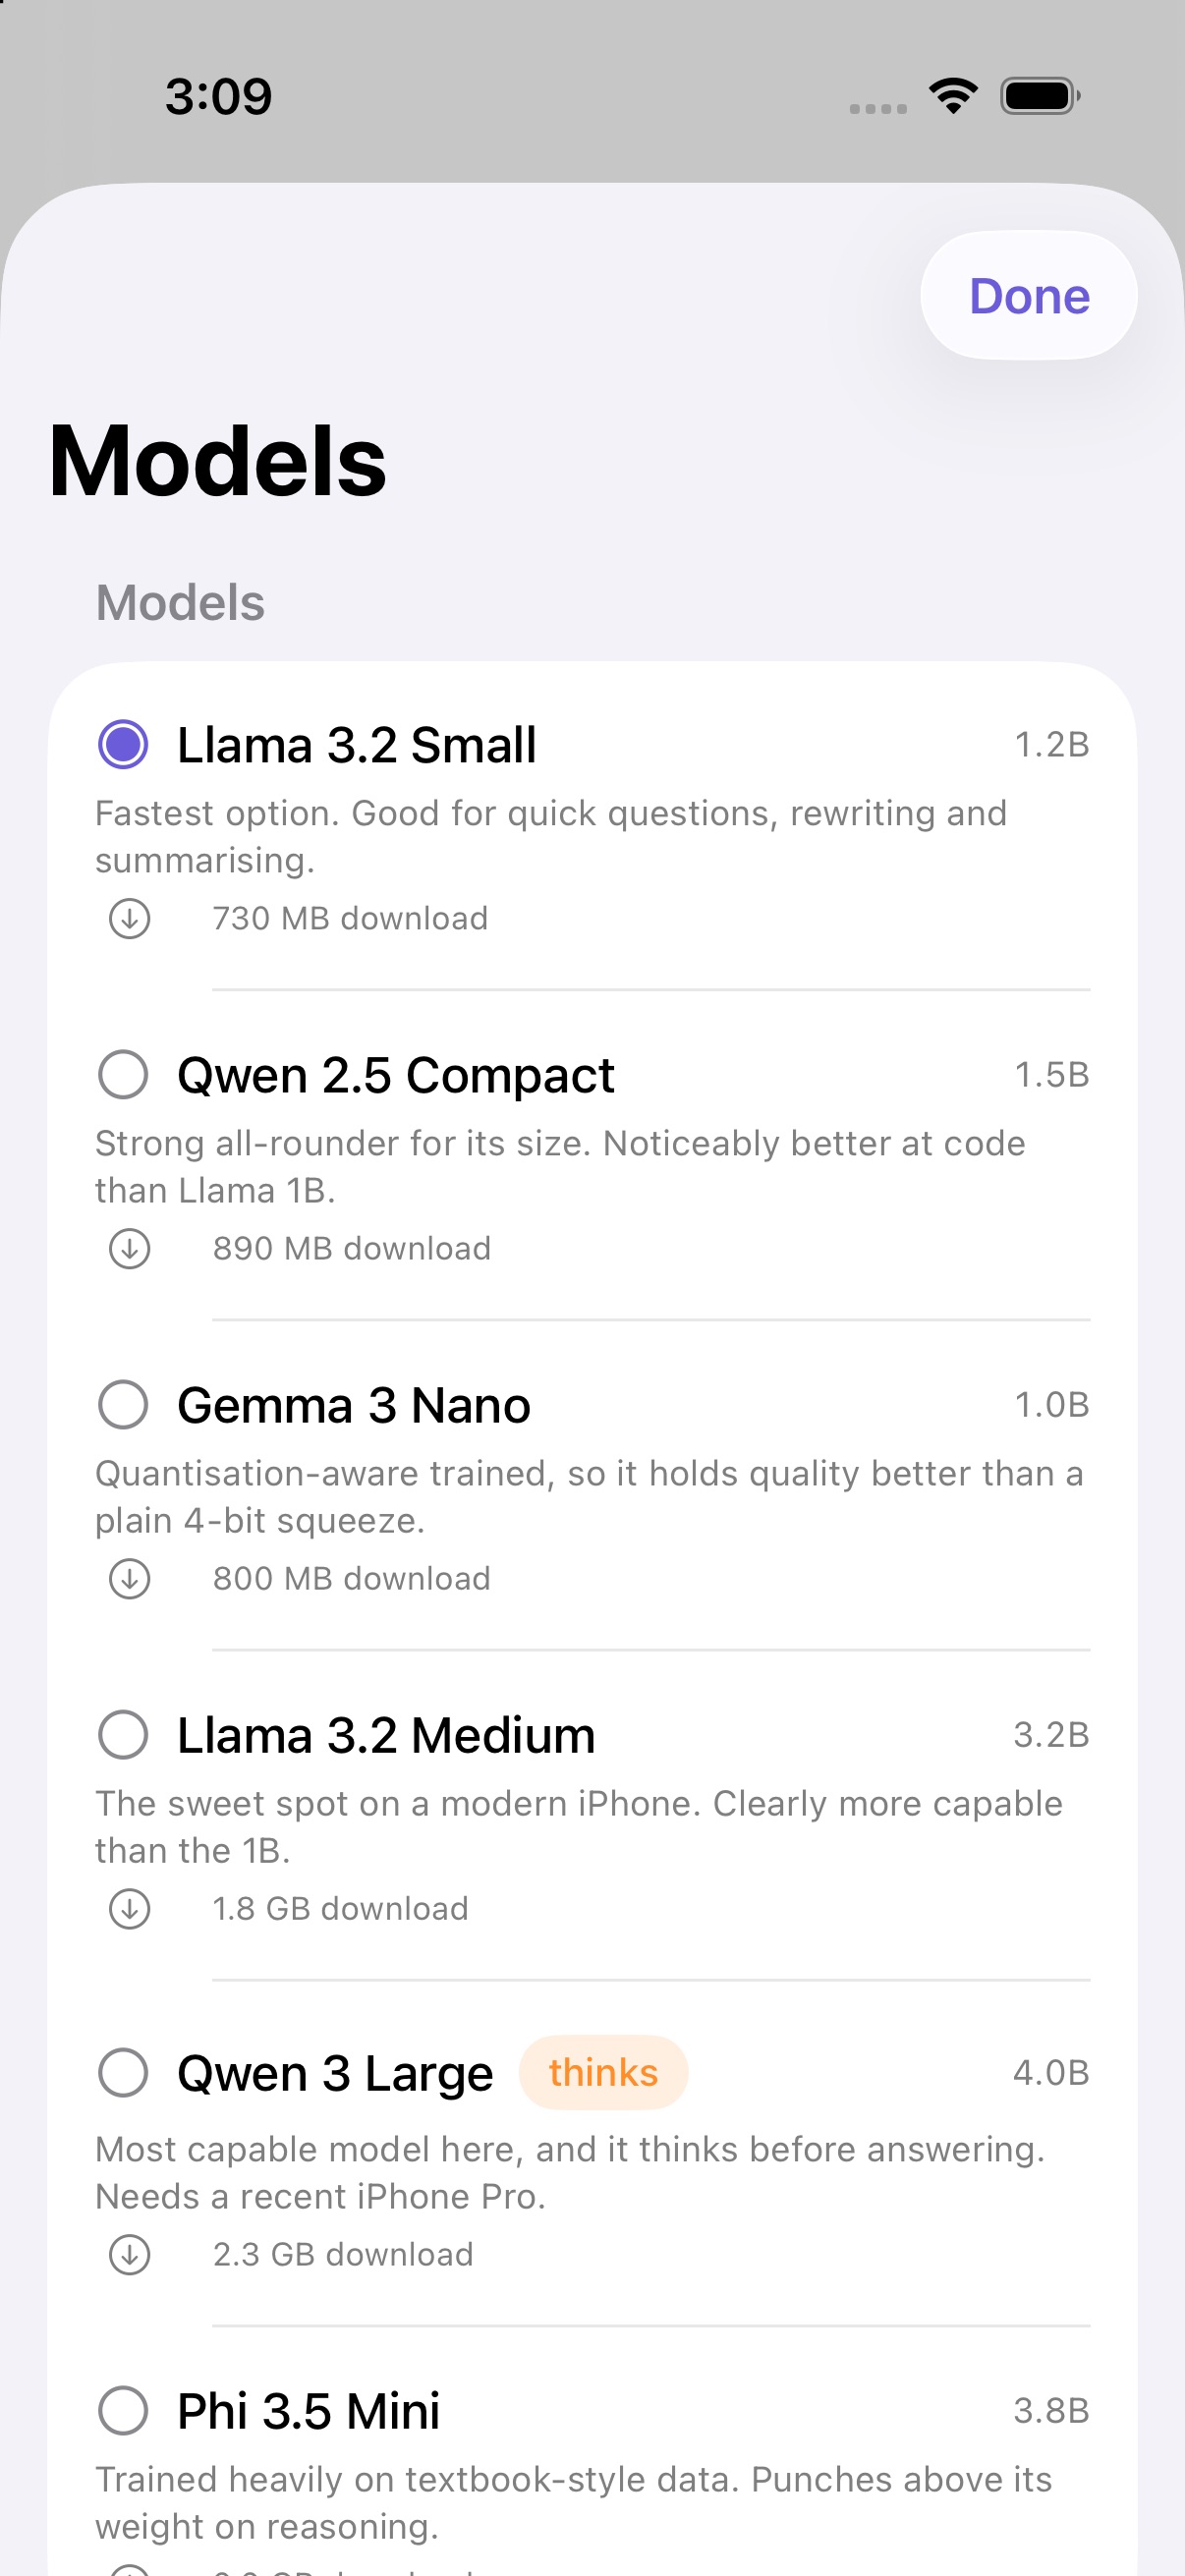
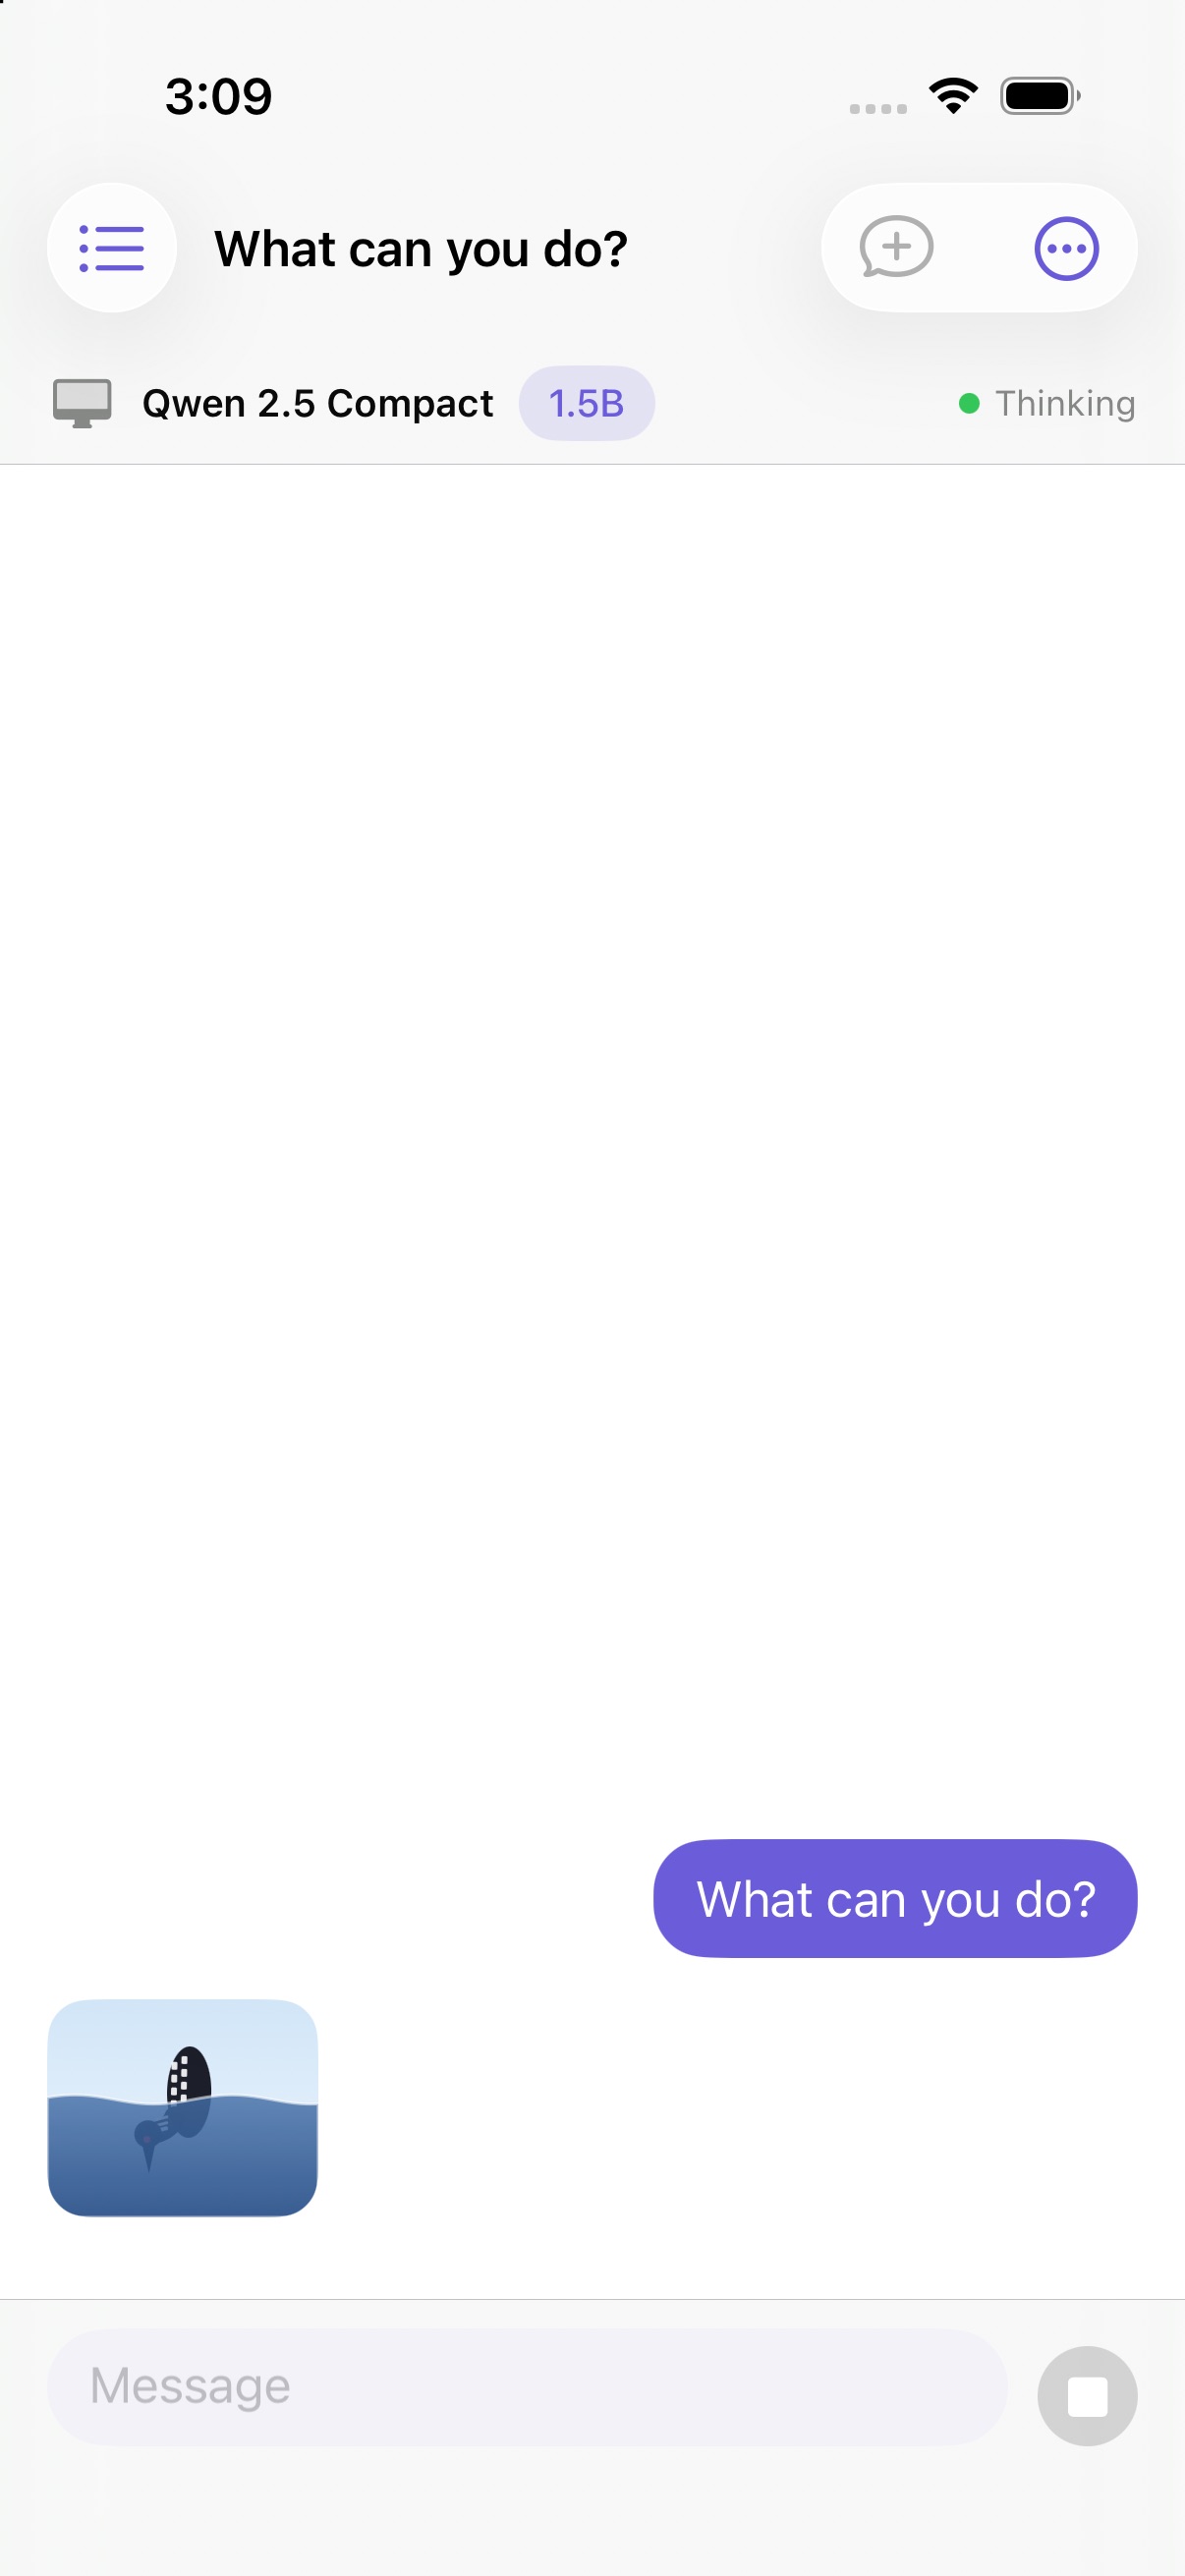
Actual iOS app screenshots, captured in the simulator. Inference runs on the iPhone's own GPU on a physical device.
Why LoonAI
The most private AI is the one that never phones home.
Every chat app sends your words to someone's server. LoonAI doesn't have a server. The model's weights live on your phone, the math runs on your silicon, and your conversations are exactly as private as your camera roll.
- Truly on-device4-bit quantised open-weights models running through Apple's MLX on the iPhone GPU — airplane mode is a feature.
- A model for every phoneFrom a 730 MB Llama for quick questions to a 2.3 GB Qwen that reasons before answering.
- Streaming, measuredToken-by-token streaming with real tokens-per-second readouts — and a stop button that actually stops.
- Nothing to leakNo account, no analytics, no cloud. Conversations are stored on the device, full stop.
Your words. Your silicon.
LoonAI is heading to TestFlight — ask for access.
Request TestFlight access